26 Aug 2013Thanks to doxie and dropbox, I'm going the paperless way. Every important paper I get in my physical mailbox, I now scan and put on the cloud. I have been doing it for bills, medical papers, tickets, warranty and am now even doing it for Ikea instruction booklets.
This way, when I'll be moving to a new appartement, I'll still be able to dismantle and rebuild my furniture, even if they have gone out of production.
As a gift, here are the links :
22 Jul 2013After one year in New Zealand, I'm now back in Paris. The trip to New Zealand was one of the best years of my life, I discovered so many things and places, met so many people, that it changed me in more ways that I can really count. It also greatly influenced the way I want to work.
Being back in Paris, I now need to find a new job. I could go back to freelancing, but I don't really want to. Freelancing had its advantages, but also some important downsides. The biggest one being that you're mostly working alone, and jumping from one project to the next.
I now want to work in a team, to teach, and to learn. Sharing with others what I know and learning from them what I don't is one of the most important things I'm now looking in my job.
I also want to be working on one big project instead of countless small ones. When you're freelancing, you're working on a project for weeks or months, creating a website from scratch and making it take a life of its own, line after line. But in the end, you hand it over to the guy who paid you to do it. And you never really get to see it growing. I now want to work on a project that I'll be able to follow, fix, and improve, days after days once it is launched in the world.
In New Zealand, I have been a WWOOFer (Willing Worker On Organic Farms) for over 8 months. All this was possible through the wwoofing website. Now, back in France I extensively use services such as couchsurfing, airbnb or blablacar. I love the way those websites allow people to meet through their services. I've met very interesting people thanks to that and I'd love to work for a company that can help linking people together.
On a more technical-oriented side, I also want to change my tools. I've been making websites for the past 10 years, coding the server side part in PHP. I now want to try something else. I used my time in New Zealand to learn a new language on my own. I first tried Python, but couldn't really go anywhere with it. I then tried Ruby and this was like discovering a new world. Writing and reading Ruby seems like writing and reading prose. I haven't yet build any website with Ruby, but coming from a cakePHP background, I guess Ruby on Rails will seem natural to me. I now use Ruby extensively for my own scripting, be it for changing a subtitle .srt fps, automatically synchronizing my cellphone files with my laptop, batch updating my mp3 tag collection and mostly any tedious task that involves scripting on my day-to-day life. I haven't got the chance to try node.js yet, but that's definitely next on my todolist.
Following the same idea, I also want to get to better use git and its collaborative features. I've only used subversion in a team, and the experience wasn't that great. Or I've used git, but only for myself as I was the only developper and I'm sure I only used it to barely 10% of what it could do. I've also tried to follow the TDD principle of writing tests first and then the code to make the test pass. I managed to do it once or twice, but the whole process seemed so long and difficult that I'm pretty sure I've missed something here, and would like to have someone to show me how they do it.
On a related note, I now try to free as much code as I can through open- source, but I'd like to do even more. I currently only share small scripts without tests and with scarce documentation. I know I could do better than that, but I'll need someone to show me the way.
I've managed to switch from Windows to Ubuntu in the past years and can't imagine going back. Working with your filesystem from inside a terminal and writing scripts to make your life easier is so powerful that I cannot go back to a GUI OS now. I've also ditched a classical IDE, namely Komodo Edit, for something different, namely vim. The switch has been hard at first, but now all the vim keys are binded to my muscle memory and I love vim for all the exact same reasons I love a terminal : you can script your tasks !
This is only a small subset of the technical changes I've already made or am currently making. I'd like to find a job where I'm hired, not for my past skills, but for the skills I want to develop. I currently have a resume where I can attest extensive experience with PHP, but that's not what I want to do in my future. What I want to do is, obviously, not on my resume. That is currently the tricky part I have to face when looking for a job.
As you can see, I have a pretty good picture of the kind of place I want for my next job. Luckily, I'm living in Paris, with a lot of job opportunities and I'm pretty sure I'll manage to find a place that match most of it. If you're currently hiring, and my expectations meet yours, don't hesitate to shoot me an email.
21 Nov 2012When I started working as a professional web developer, I wasn't using any versioning system. When I needed to add a new feature to an existing website, I just coded it and then uploaded it by FTP.
Sometimes, it turns out that the feature was a failure, and that I needed to get back to a previous version. Most of the time, I remembered the old feature and could just type the old code back. Other times, I couldn't and getting the website back to its previous state was a nightmare.
So whenever I felt a feature could go wrong, I started creating manual backup of files before editing them, prefixing them with -version2 and such. It worked ok at first, but after some time, it was impossible, even for me to tell the different versions appart.
I also started to realize a trend on the web, reading from other developers, that there was something call a version-control system. I thought I needed to use one of them, to keep track of different version of files.
I wasn't exactly sure which one was right for me, so I asked a few friends. Most of them told me they were using Subversion at work, but that it had a few shortcomings, but that it was still better than nothing. Another friend told me that he was using Mercurial, both for personal projects and at work, at that his whole team was actually versioning everything with it and were very happy about it.
First steps with mercurial
So I thought I should start using Mercurial. If I have to learn a new tool, I'd rather take one that works well and where I have a friend able to help me on my first steps.
Back in these days, I was still using Windows so I downloaded and installed Mercurial and its GUI version, TortoiseHG. I was quite happy with it the instant I installed it. I could just "commit" (which was a new word for me) my changes and know for sure that they were safe and that I could get back to previous versions of my file easily.
I was committing all my changes at the end of each day, writing a long commit message listing everything I had done in that given day. Then, the next morning I could just re-read the previous commit message and remember what I was doing. The commit message worked a bit like a todo list for what needed to be done.
I was mostly using Mercurial as a backup system. I even opened an account on BitBucket where I uploaded my changes every day, in the case my laptop crashed, I still had backups of everything online.
A little note about FTP
Using Mercurial had another benefical side-effect on my productivity. It made me discover how backward FTP upload was. Before using Mercurial, when I needed to add changes to a website, I connected to the server with FTP and transfered every changed files from my local machine to the server.
Of course, I had to remember which files I changed, and upload them one by one. This was tedious. I had to move from directory to directory before copying the files. I can't tell you how many times I had a bug in production that I couldn't replicate on my local machine, just because I either forgot to upload a file or uploaded it in the wrong place.
Sometimes just to be sure to upload all the files on their correct places, I simply uploaded the full website directory and let the FTP software choose if they needed to be updated or not. But this took ages as the software had to send a request to compare timestamp modification date for each file.
And if I only had two files changed, I had to wait for the FTP to scan each file between the first and the second one before it gets uploaded. This too resulted in bug reports from customer that I couldn't replicate, even on production because by the time I get to check the website, the missing file that was causing the error had been uploaded and everything worked perfectly for me. In the end, it created a list of "ghost bugs" that I was never sure if they were real bugs or created by the FTP upload lag.
Mercurial get rid of all this crap because it was clever enough to know which files were changed from the last deployment, and even which part of the files where changed, sending only the difference. This resulted in much faster upload time and no more errors in missing files. Also, I got bonus security points for transferring through ssl and not clear text FTP.
Sorry for this little FTP disgression. Anyway, as you remember I was using Mercurial as a backup system more than a version-control system. Commiting once a day became cumbersome as I wanted more fine-tuning on what I commited. I ended up commiting twice a day, or even every time I took a break, but then I realized it made much more sense to commit based on feature and not on time.
No more Mercurial
And that's when Mercurial started to get in the way. I often worked on a feature and while doing that, spotted tiny bugs or typos that I fixed while working on the big feature. I wanted to commit only related changes together, and didn't manage to do that well with Mercurial.
I guess this is because I did not really understand how Mercurial worked back in these days, but to be honest I do not understand it better now. Whenever a file is modified in Mercurial, it is ready to be added to the next commit. But when you create a new file or delete one, you have to tell Mercurial that you want this add/delete to be registered in the next commit.
As I said, I sometime just fixed small bugs or typos in files that had not much to do with the feature I was working on at that moment. I would have like to be able to commit only these files, and not the others. I never really managed to make it correctly with Mercurial so in the end I was still commiting more files that I wanted to.
That's when I considered trying git instead of Mercurial. I made some googling on "git vs Mercurial" to see how they differ and the general consensus seems to be that git is more low level than Mercurial. Git has a plethora of commands, most of them you'll never use, while Mercurial is focused on a workflow for the end user that works well. Also, git allow the user to rewrite its history.
After reading all this I was convinced Mercurial was the right tool for me. I was still struggling with my current version system, I didn't want to try one that was even more hard to understand. Plus, rewriting history ? I don't want that to happen in real life, I sure don't want that to happen with my files either.
So I digged deeper in Mercurial, trying to understand it better, to grok it but no, really, I still could'nt make it behave the way I'd like to work with my files so I finally decided to give git a try.
First steps with git
Because there was this thing named github, and all the cool kids where on github, and I too wanted to participate in those big open source projects and I felt like I was held back by the tool I was using.
On my first hours of using git I managed to do what I had struggled to do with Mercurial for so long. I could easily choose which files to commit or not and split my work in several commits. Of course, I could never have done it without google. Git man pages are gibberish and the command line commands and options list is so vast I felt lost. Even when I found what I needed I wondered why the git developers choosed to give them such abstract names without any apparent cohesion in the complete git API.
I had to create aliases to do my day to day tasks with git so as not to remember and type all these crazy commands, but in the end it turns out ok. I keep running into problems, but none that the help of google, StackOverflow and the incredibly rich git API can't solve.
I'm now versioning any new project with git and even converted some old projects from Mercurial to git. I know I'm still in the early stages of learning git (I've only started using branches extensively since a few weeks) but I do really enjoy it a lot.
What's next ?
I've done all my git training by myself, while in New Zealand for a year, away from work and just for fun. I know that when I'll get back to Paris and start looking for a new job I'd like to find a place where the day-to-day workflow involves git because I really want to see the way branching and merging helps people work together building bigger things.
06 Sep 2012Here is a little script I hacked together to display in your terminal all the colors available in the 256 color spectrum, as well as a visual representation of them.
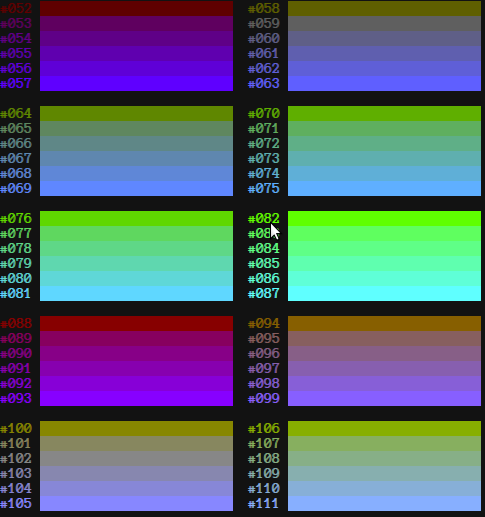
The oh-my-zsh project actually ships with a method named spectrum that does pretty much the same thing, but I found that it was hard to actually get a real feel of what the color where with the original output. So I coded this one.
It does not display the colors in the range {000..015} because those are dependent on your terminal configuration. Also, the output is split in blocks of 6 lines, with 2 blocks displayed side by side. You can modify those values in the script if you want to make it easier to read on you screen. I use 2 and 6 because it is what is the more readable on my tiny netbook screen.
Ok, enough talk, here is the script
#!/usr/bin/zsh
# Display the terminal 255 colors by blocks

# Long space is long
local space=" "
for i in {0..22}; do space=$space" "; done

# Number of color lines per block
local lines=6
# Number of blocks per terminal line
local blocks=2

# Tmp var to hold the current line in a block
local m=0
# Tmp var to hold how many blocks are filled
local b=0
typeset -A grid

# We want to display the blocks side by side, so it means we'll have to create
# each line one my one then display all of them, and after that jump to the
# next set of blocks
for color in {016..255}; do
    # Current line in a block
    m=$((($color-16)%$lines))

    # Appending the displayed color to the line
    grid[$m]=$grid[$m]"^[[01m^[[38;5;${color}m#${color} ^[[48;5;${color}m${space}^[[00m  "

    # Counting how many blocks are filled
    [[ $m = 5 ]] && b=$(($b+1))

    # Enough blocks for this line, display them
    if [[ $b = $blocks ]]; then
        # Reset block counter
        b=0;
        # Display each line
        for j in {0..5}; do
            echo $grid[$j]
            grid[$j]=""
        done
        echo ""
    fi
done

# Display each remaining blocks
for j in {0..5}; do
    echo $grid[$j]
    grid[$j]=""
done
Oh and one last word. You might want to pipe the output to less to make it easier to read if you're on a small screen like me.
30 Aug 2012I recently switched to git as my main version control system (I used to use Mercurial before that). I quickly grasped the concept of the staging area and used the git add command extensively to add before committing.
And zsh ships with nice git autocompletion features, and suggests files to add with git add when you press Tab.
Git unstage
What is missing from the basic git commands is a way to unstage a file from the staging area. Well, I can do it with git reset HEAD, but this command is a bit tedious to type.
So I created an alias, named git unstage that does just that. I just added the following lines to my ~/.gitconfig, under the [alias] header :
I can now easily add files to the staging area with git add and remove them with git unstage
Autocompletion
At this point, git unstage autocompletion does not work. It simply suggest all files in the current directory, while I'd like it to suggest only files in the staging area.
When you create a git alias, you cannot simply add a zsh autocomplete method for that alias (meaning, you cannot create a _git-unstage method), you have to hook your custom autocomplete logic to the underlying git method your alias refers to. In this case, this is the git reset method.
So, I created my own _git-reset autocompletion function. Actually, I borrowed the one already defined in /usr/share/zsh/functions/Completion/Unix/_git and tweaked it a little bit.
I created a file named _git-reset and put it in my $FPATH so zsh will load it when asked for autocompletion and it will overwrite the _git-reset method already defined in _git.
Here is the full content of the file :
#compdef git-reset

_git-reset () {
    local curcontext=$curcontext state line
    typeset -A opt_args

    _arguments -C -S -A '-*' \
            '(-q --quiet)'{-q,--quiet}'[be quiet, only report errors]' \
            '::commit:__git_revisions' \
        - reset-head \
            '(        --soft --hard --merge --keep)--mixed[reset the index but not the working tree (default)]' \
            '(--mixed        --hard --merge --keep)--soft[do not touch the index file nor the working tree]' \
            '(--mixed --soft        --merge --keep)--hard[match the working tree and index to the given tree]' \
            '(--mixed --soft --hard         --keep)--merge[reset out of a conflicted merge]' \
            '(--mixed --soft --hard --merge       )--keep[like --hard, but keep local working tree changes]' \
        - reset-paths \
            '(-p --patch)'{-p,--patch}'[select diff hunks to remove from the index]' \
            '*::file:->files' && ret=0

    case $state in
        (files)
            local commit
            if [[ -n $line[1] ]] && __git_is_committish $line[1]; then
                commit=$line[1]
            else
                commit=HEAD
            fi
            # Suggest files in index if `git reset HEAD`
            if [[ $line[1] = HEAD ]]; then
                __git_changed_files
            else
                __git_tree_files . $commit
            fi
            ret=0
            ;;
    esac
}

_git-reset "$@"
As you may have noticed this script is an almost exact copy/paste from the original _git-reset script. The only modification I've done is in those lines :
# Suggest files in index if `git reset HEAD`
if [[ $line[1] = HEAD ]]; then
    __git_changed_files
else
    __git_tree_files . $commit
fi
What it does is checking the first argument of git reset, and if it's HEAD, it suggests files in the staging area (__git_changed_files) instead of files in the current repo (__git_tree_files).
It took me quite a bit of time to figure out which method to use to get files in the staging area as I had been looking for a __git_staged_files for quite a while and finally discovered that the __git_changed_files was actually what I was looking for.
Conclusion
The git unstage alias is quite common, you can find it in a lot of books and websites teaching git. But it becomes much more usable once zsh does the autocomplete for you and you can easily select files to unstage that way.